VeroCloud


VeroCloud offers high-performance GPU & CPU compute, along with Tally on Cloud services, tailored for businesses in India. Get scalable, secure, and cost-effective cloud solutions with seamless deployment. Power your workflows with VeroCloud! VeroCloud offers GPU-powered cloud hosting and high-performance server for AI, deep learning, and data analytics. With NVIDIA GPUs, we deliver intence speed, scalability, and reliability, ideal for teams needing powerful, scalable cloud infrastructure. Get set up instantly with optimized environments for GPU Cloud, HPC Compute, or Tally on Cloud, and configure your system to match your specific workload needs.
VeroCloud provides high-performance GPU & CPU compute and cloud solutions for businesses in India.
- AI and deep learning model training
- Data analytics and high-performance computing
- Deploying HPC workloads
- Running Tally on Cloud
- Scaling AI inference
- Serverless scaling of AI models
- Get started instantly with optimized environments for GPU Cloud
- HPC Compute
- or Tally on Cloud
- and configure your system to match your specific workload needs. You can also create and customize your own templates for seamless deployment across all your computing resources.

The web performance & security company

A modern, visual file manager for the terminal

Sync your mailbox with your issue tracker

Caps Lock keeps your Mac awake, even with the lid closed

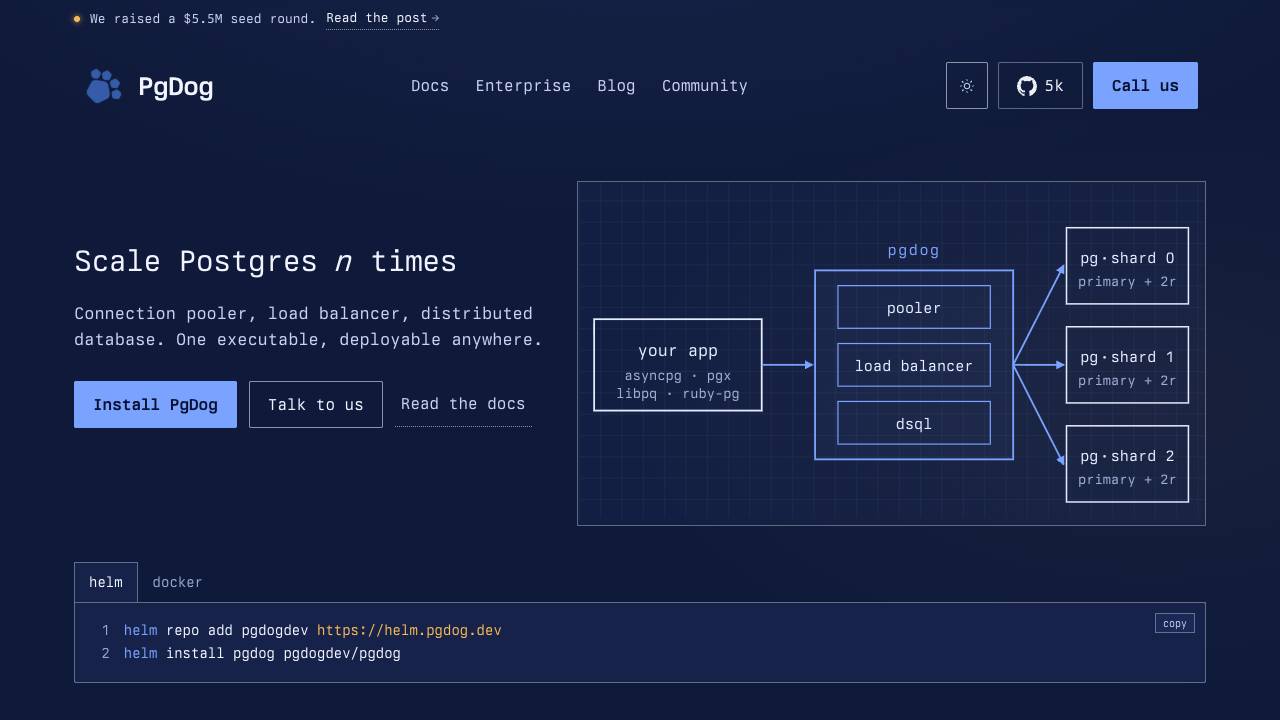
Scale PostgreSQL without changing your app

The Web Data API for AI Agents and Developers

The open source Ahrefs alternative

Catch API drift before your customers do

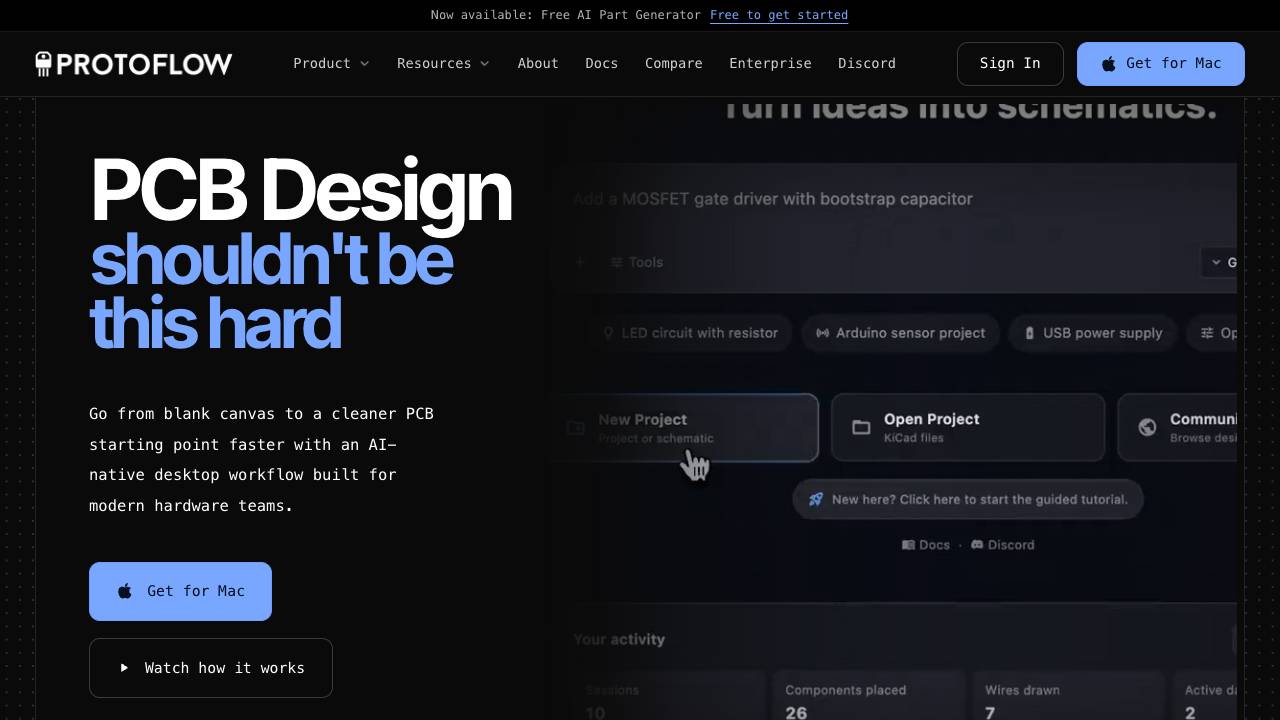
AI-powered schematic design tool for PCB making

Comment on your AI agent's code & collaborate on changes

Manage your team of AI agents by voice, from anywhere

Annotate anything for humans and their agents

The AI database client for Mac

Give Claude Code and Codex a voice

Your time travel debugger

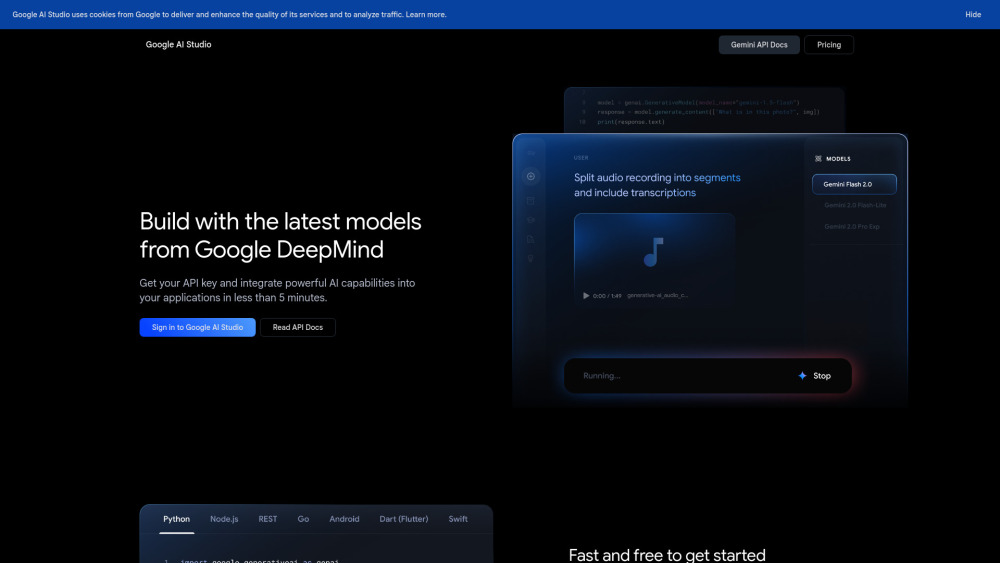
Platform for building with Google's Gemini AI models.

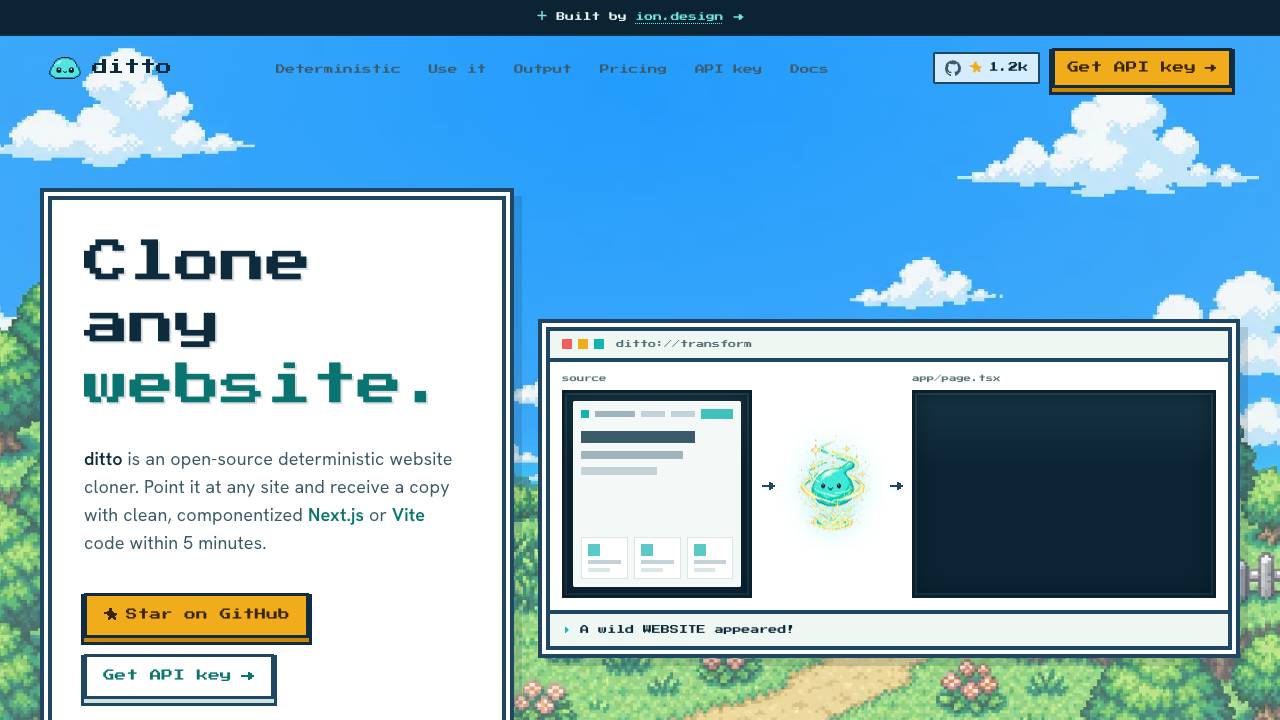
Clone any website into clean code. Free & open source

A private data-usage meter for your Mac menu bar